Data engineering
From listening data to recommendations
An end-to-end music recommendation prototype connecting data ingestion, scheduled model workflows, and an interactive dashboard.
The question
What does it take to turn track metadata and a small amount of listening history into a repeatable recommendation workflow?
My contribution
Exploratory analysis, Airflow DAGs, Streamlit dashboard, recommendation model, and team coordination, shared with teammates as documented in the repository.
The approach
- Combined public track metadata with generated users and synthetic listening events.
- Used Airflow to orchestrate data ingestion, embedding generation, and recommendation updates in a PostgreSQL-backed pipeline.
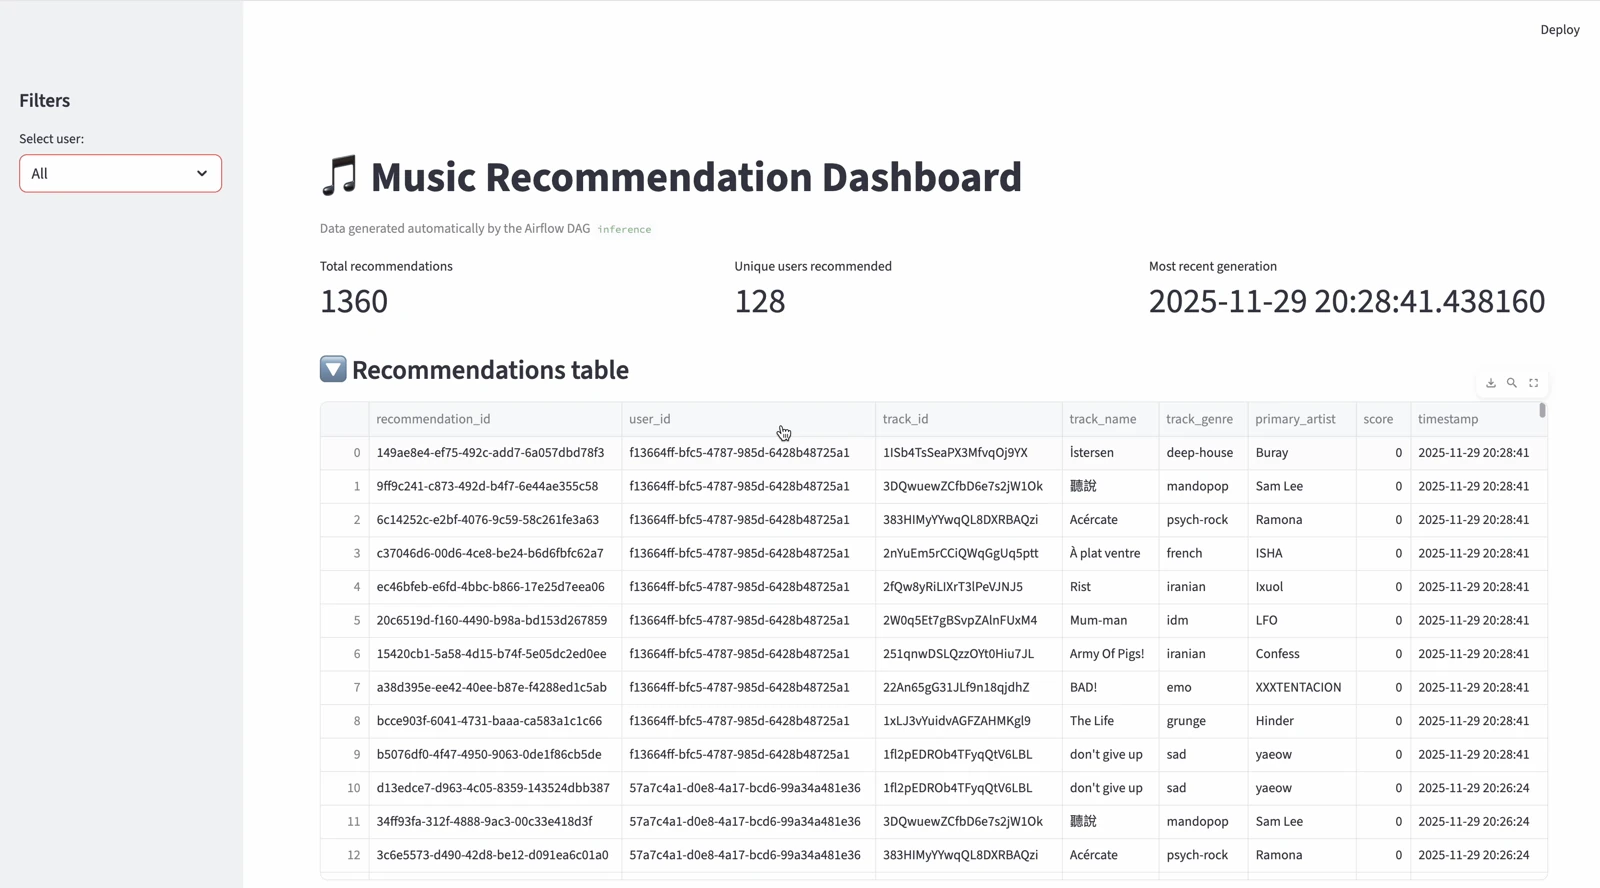
- Presented results through a Streamlit dashboard, with Python tests and workflow-level validation supporting the pipeline.
What this explores
The prototype connects the modeling step with the engineering around it: data preparation, scheduled inference, persistence, validation, and a usable interface for exploring recommendations.
Scope & limitations
Listening histories are simulated. The content-based model does not establish recommendation quality for real users, and the synchronous inference approach has not been validated for large user populations.
Team: Jordan, Aesha, Ammy, and Tonantzin. The repository documents shared responsibilities for the model, orchestration, dashboard, and testing.
Project summary and attribution are based on the repository documentation.